Blog

Page 32 of 60

All Articles

Insights on AI, machine learning, and technology strategy

LangChain Open SWE Shrinks the Gap Between Enterprise Coding Agents and Everyone Else
Industry Insights·

LangChain Open SWE Shrinks the Gap Between Enterprise Coding Agents and Everyone Else

LangChain put Open SWE back in focus on March 17, 2026, reviving the open-source case for internal cloud coding agents that spin up isolated environments, stay clean on context, and parallelize real engineering work.

4 min read
GPT-5.4 Mini and Nano Turn Coding Agents Into a Cost Discipline
Industry Insights·

GPT-5.4 Mini and Nano Turn Coding Agents Into a Cost Discipline

OpenAI's new GPT-5.4 mini and nano bring faster coding, stronger computer use, and 400k context into the cheap-model tier, giving agent builders a much cleaner cost curve.

4 min read
Everyone covered Unsloth Studio's 2x training speed. The useful part was the dataset pipeline.
Industry Insights·

Everyone covered Unsloth Studio's 2x training speed. The useful part was the dataset pipeline.

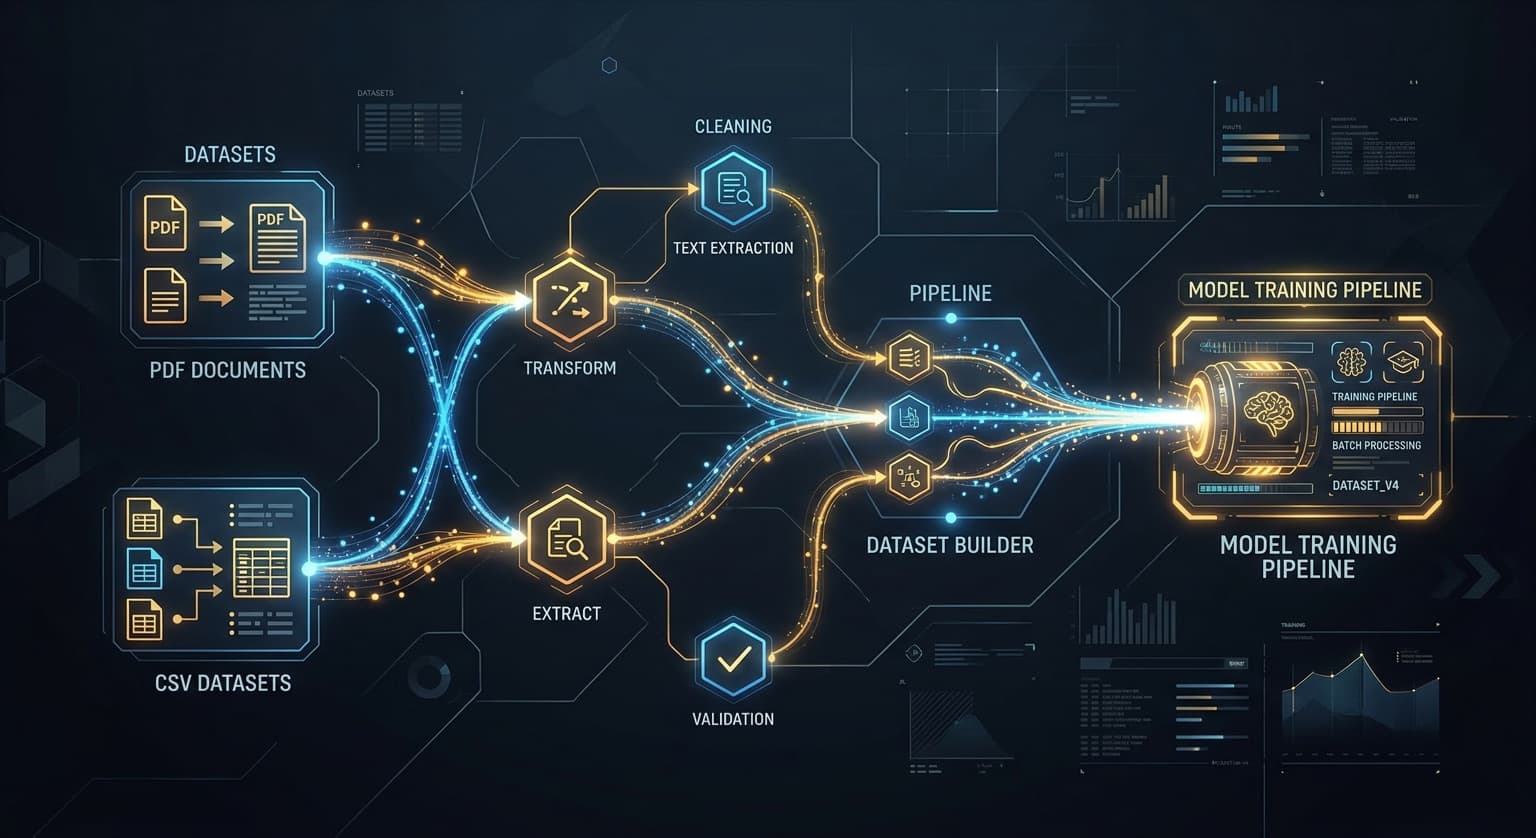
Unsloth Studio launched with a local training UI and 2x speed claims. The buried feature is Data Recipes — a visual node-graph dataset builder powered by NVIDIA DataDesigner that turns PDFs and CSVs into fine-tuning datasets without writing code.

4 min read
AI Keeps Making Up Business Facts. Rumored.ai Is Built to Fix That.
Small Business AI·

AI Keeps Making Up Business Facts. Rumored.ai Is Built to Fix That.

Rumored.ai launched today as a tool that audits what AI models say about your brand, identifies factual hallucinations, and generates a prioritized fix plan. It covers 12 audit sections including competitive analysis, schema audit, and active threats.

5 min read
119B Parameters, 6.5B Activated: Mistral Small 4 Collapses Three Open Models Into One
Industry Insights·

119B Parameters, 6.5B Activated: Mistral Small 4 Collapses Three Open Models Into One

Mistral AI released Mistral Small 4 on March 16, 2026, with 119B total parameters, 128 experts, 6.5B activated per token, a 256K context window, configurable reasoning, and an Apache 2.0 license.

4 min read
NVIDIA Dynamo 1.0 turns inference into an operating-system problem — and every major cloud provider just signed up.
Industry Insights·

NVIDIA Dynamo 1.0 turns inference into an operating-system problem — and every major cloud provider just signed up.

NVIDIA released Dynamo 1.0 at GTC 2026 — open source inference software it calls the 'OS for AI factories.' AWS, Azure, Google Cloud, and OCI are adopting it. Blackwell GPU inference performance jumps up to 7x.

4 min read
Adobe and NVIDIA just moved creative AI past image generation and into the production system.
Industry Insights·

Adobe and NVIDIA just moved creative AI past image generation and into the production system.

Adobe and NVIDIA announced a strategic partnership at GTC to build next-generation Firefly models, agentic creative and marketing workflows, and a new Omniverse-based 3D digital twin system. The real story is not one more model launch — it is Adobe wiring NVIDIA infrastructure directly into the tools, asset pipelines, and brand controls that enterprises already use to ship work.

4 min read
5 Trillion Tokens per Day: GPT-5.4's API Ramp Is an Adoption-Velocity Record
Industry Insights·

5 Trillion Tokens per Day: GPT-5.4's API Ramp Is an Adoption-Velocity Record

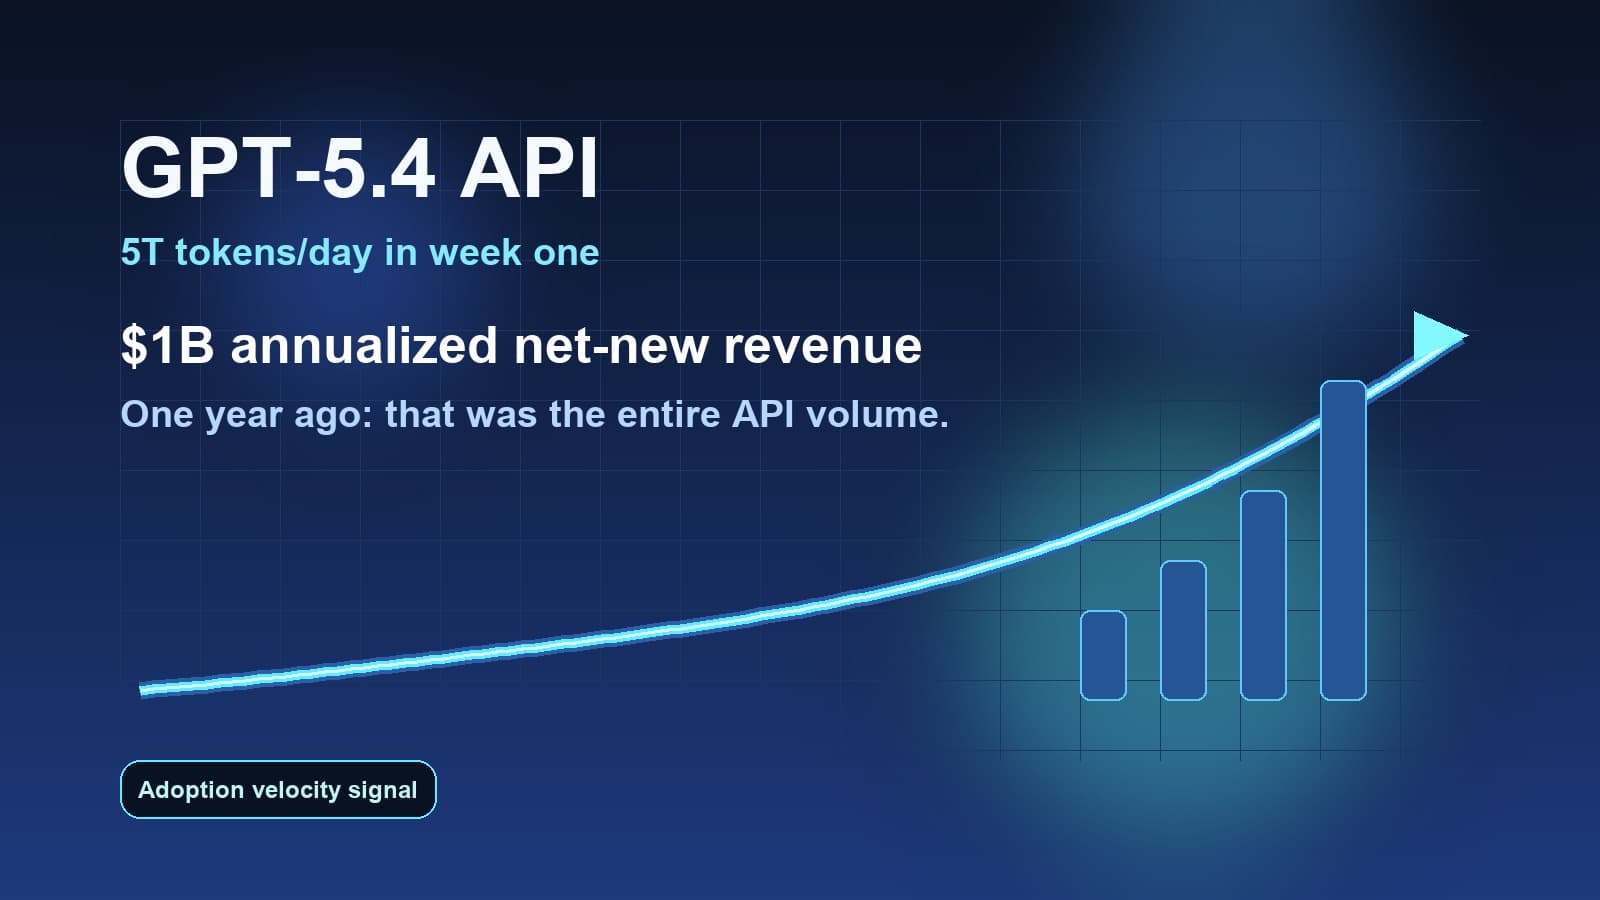
GPT-5.4 hit 5 trillion tokens per day within one week of its API launch -- exceeding the entire OpenAI API volume from a year ago and putting the model on a $1B annualized net-new revenue run rate.

5 min read
Andrew Ng Announces Context Hub, an Open-Source CLI for Current API Docs in AI Coding Agents
Industry Insights·

Andrew Ng Announces Context Hub, an Open-Source CLI for Current API Docs in AI Coding Agents

Andrew Ng's new open-source Context Hub CLI gives AI coding agents current API docs, local memory, and doc feedback loops to cut stale-call errors.

5 min read
The MCP token tax no one quoted: 44,000 tokens to check one repo language
Industry Insights·

The MCP token tax no one quoted: 44,000 tokens to check one repo language

A controlled benchmark found MCP costing 4 to 32× more tokens than CLI for identical operations. NVIDIA's Vera CPU launched with 88 custom cores and 22,500 concurrent agent environments per rack. Mistral's Leanstral beat Claude Sonnet 4.6 on formal proof benchmarks at one-fifteenth the price.

5 min read
Mistral and Nvidia just put a 675B model on a 41B budget
Industry Insights·

Mistral and Nvidia just put a 675B model on a 41B budget

Mistral AI joined Nvidia's Nemotron Coalition at GTC 2026 and helped build the open base model behind Nemotron 4. The headline number is 675B parameters, but the practical number is 41B active per query.

4 min read
Nvidia's 35x inference number lost its denominator on the way to the headline
Industry Insights·

Nvidia's 35x inference number lost its denominator on the way to the headline

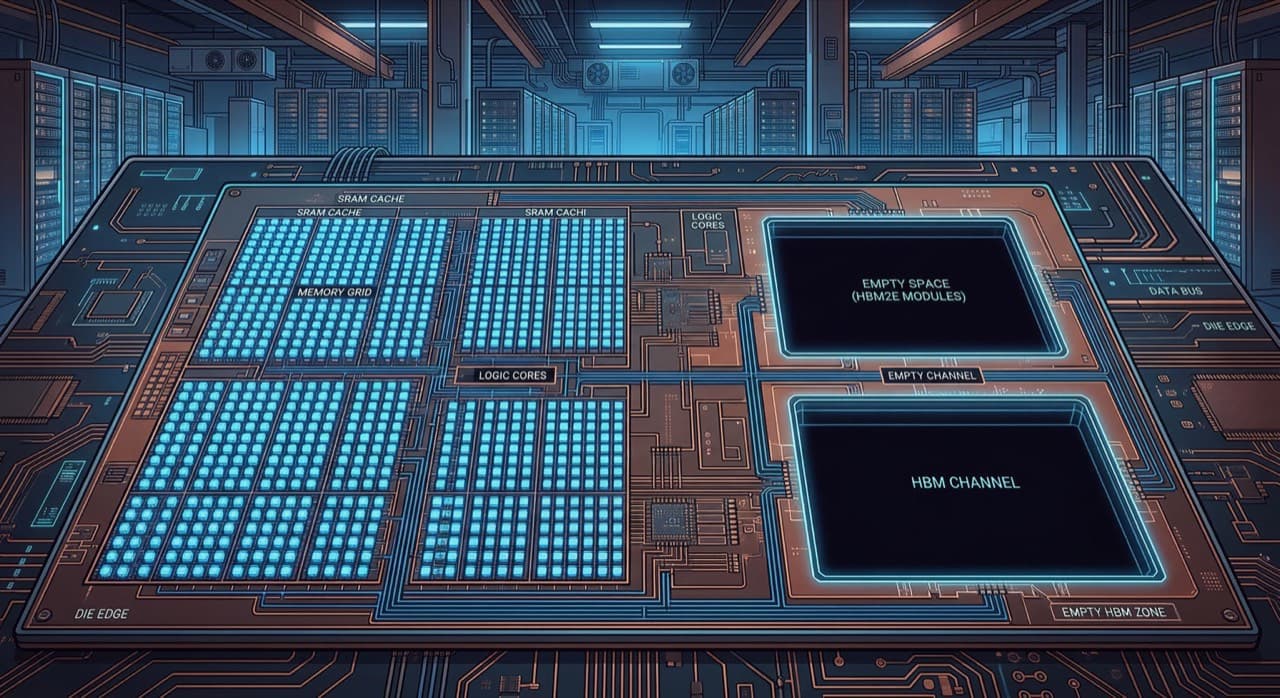
Nvidia's Groq 3 LPX claims 35x inference throughput, but the unit is per megawatt, not absolute. The real story is 128GB of on-chip SRAM replacing HBM entirely — a supply chain end-run hiding inside a performance slide.

4 min read